Private GPT deployment is production-ready for enterprises today, provided you build it gateway-first rather than model-first. A working setup routes every request through an authentication and audit layer with SSO, runs on a serving engine you can swap without breaking downstream tools, optionally layers in retrieval with access controls, and reports into monitoring from day one. Once the hardware is sized correctly, getting from a bare server to a logged, authenticated internal endpoint takes about one engineer-week. The two things that sink these projects are skipping the gateway and leaving egress open by default.
TL;DR:
- Private GPT deployment requires a gateway handling SSO, revocable API keys, audit logging, and strict egress control for compliance.
- Ollama suits small teams and pilots, while vLLM is better for high-concurrency, batch processing with more operational complexity.
- GPU sizing depends on VRAM, context length, and concurrency, with 20 to 120 GB of NVMe storage needed per model to ensure flexibility and rollback capability.
- Security must include role-based access, request logging, egress blocking, and input-output filtering, with data retention policies set upfront for compliance.
- Deployment typically takes about one week per server, with common pitfalls being hardware underestimation, driver mismatch, and delayed policy decisions.
Table of Contents
- What Does a Production Private GPT Architecture Look Like?
- Ollama or vLLM: Which Runtime Should You Run?
- How Do You Size GPUs and Storage for Private LLM Hosting?
- What Security and Compliance Controls Does Private GPT Need?
- How Should RAG Respect Enterprise Data Access Rules?
- What’s the Realistic Timeline to Deploy a Private LLM?
- What Should You Monitor Once Private GPT Goes Live?
- How Autonomousfirm Partners With Enterprises on Private GPT
- Perspective: When Self-Hosting Beats a Hybrid Setup
- Ready to Deploy Private GPT the Right Way?
- Sources
- FAQ
What Does a Production Private GPT Architecture Look Like?
Every durable on-prem deployment follows the same shape: users and applications hit a gateway, the gateway talks to a serving engine, the serving engine talks to GPUs, and an optional retrieval layer sits beside it feeding context into prompts. Monitoring wraps around all of it.
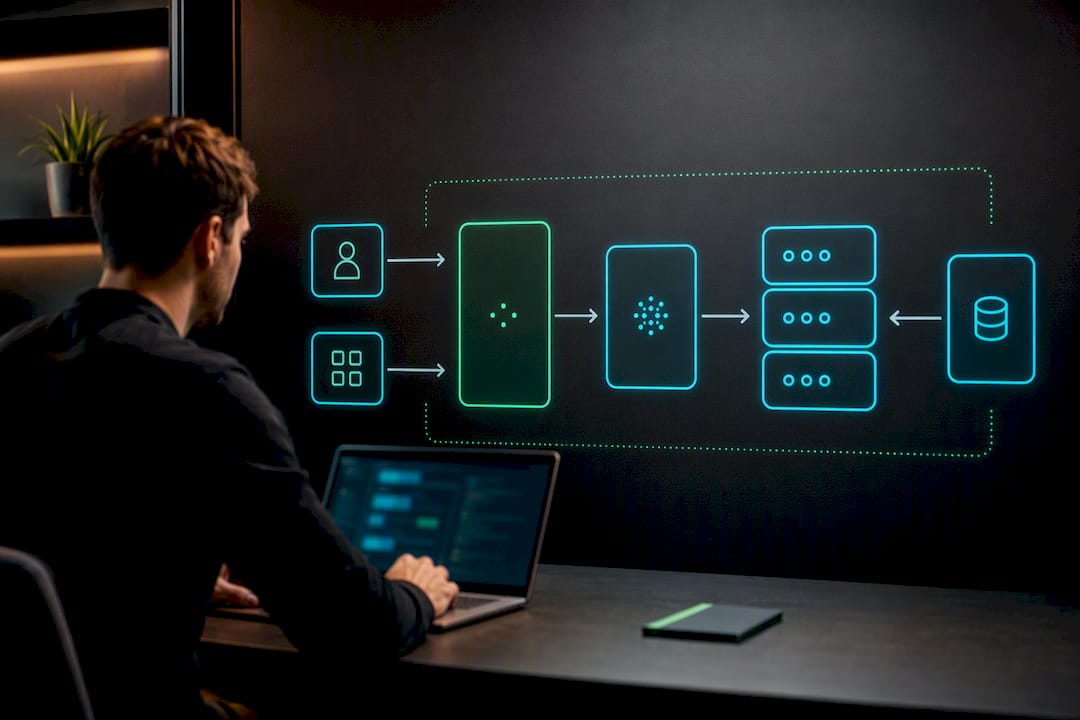
The gateway is where most self-hosted LLM projects go wrong. Teams that expose the serving engine directly almost always end up retrofitting authentication and logging after a security review flags the gap, and retrofits cost more than building it right the first time.
A gateway earns “production-grade” status when it handles:
- SSO through OIDC or SAML, tied to your existing identity provider
- Per-team API keys issued and revocable without a redeploy
- Per-request audit records exported to your SIEM
- Egress control, so the model server never talks to the open internet
- OpenAI-compatible endpoints, so internal tools don’t care which model sits behind them
If your gateway can’t do all five, it’s not ready for regulated workloads yet.
Ollama or vLLM: Which Runtime Should You Run?
Start with Ollama, move to vLLM when concurrency demands it. That’s the whole decision tree for most teams, and it holds up better than picking based on benchmarks alone.
Ollama runs as a single binary, works with GGUF-quantized models, and needs almost no operational tending. It’s the right call for development work, internal pilots, and any deployment serving a small number of concurrent light users. vLLM exists for a different problem: continuous batching and high-throughput serving when queued requests start piling up. It carries a heavier operational load, safetensors instead of GGUF, and demands more GPU memory tuning, but it’s the only realistic option once a department’s usage crosses from “occasional questions” into “constant traffic.”
The migration between them should be boring. Keep your gateway’s API contract identical across both runtimes, and swapping one for the other becomes a configuration change, not a rewrite.
- Ollama: dev, pilots, small teams, low ops burden
- vLLM: departmental+ concurrency, batching, higher ops burden
Pro Tip: Before migrating, run a compatibility check between your target model and GPU. Mismatched VRAM assumptions are the single most common cause of a failed cutover weekend.
How Do You Size GPUs and Storage for Private LLM Hosting?
VRAM math decides whether your deployment works or stalls under real traffic. Model weights need to sit resident in GPU memory, and on top of that you need headroom for the KV cache, which scales with context length and concurrent sessions. A 7 billion parameter model quantized to 4-bit might fit comfortably on a 24 GB card for light use, but push context windows longer or add concurrent users, and that same card runs out of room fast.
Storage and generational planning matter just as much as raw GPU horsepower:
- Budget 20 to 120 GB of NVMe storage per model, depending on parameter count and quantization
- Keep at least two model generations on disk so a bad rollout can roll back without a re-download
- Confirm driver versions and pin to Ubuntu LTS before ordering hardware, not after
Sizing tiers roughly break down as: a single workstation GPU for small teams testing the waters, a high-memory GPU card for department-level rollout, and multi-node or colocated GPU clusters once you’re serving the whole organization. Guess low on any tier and you’ll be back at procurement in three months.
What Security and Compliance Controls Does Private GPT Need?
SSO and audit logging aren’t optional extras layered on later. They’re the baseline that lets a compliance team sign off on the deployment at all.
- Stand up SAML or OIDC SSO against your identity provider and enforce role-based access control at the gateway, not inside the model server.
- Issue distinct API keys per user and per service account, so a leaked key maps to exactly one owner.
- Log every request with authenticated user, timestamp, model version, and a reference to the request and response, then export that schema to your SIEM with a retention period your legal team has actually reviewed.
- Block outbound egress by default on the model server and any RAG components, opening only the minimal required endpoints for updates.
- Add a content filter or classifier layer to screen inputs and outputs before they hit logs or downstream systems.
Log retention deserves its own line item. Prompts frequently contain personally identifiable information, and treating that as a compliance concern from day one rather than an afterthought saves you a painful conversation with legal later. Loop in your compliance team early enough to run a data protection impact assessment before launch, not after an auditor asks for one.
Pro Tip: Write your retention policy before you write your first log line. Changing retention rules after six months of accumulated logs is a much bigger project than setting the number correctly up front.
How Should RAG Respect Enterprise Data Access Rules?
Retrieval augmented generation only belongs in a regulated environment if it respects the same permissions your document systems already enforce. That means an embedding model running beside the LLM, a vector database such as Qdrant or pgvector, and access-control metadata stored alongside every embedded chunk, not bolted on afterward.
The filtering has to happen at retrieval time, not at display time. If a user’s role doesn’t grant access to a document, the retrieval step should never surface it as context, regardless of how relevant the embedding match looks.
- Store ACL metadata (department, classification level, owner) with every vector
- Enforce permission filters inside the retrieval query itself
- Log every retrieval event and attach provenance references to the response
- Re-index on a schedule that matches how often source permissions actually change
Skipping the ACL layer is how a well-intentioned RAG pilot turns into an internal data leak nobody notices until someone asks the assistant the wrong question.
What’s the Realistic Timeline to Deploy a Private LLM?
Six steps get you from a rack-mounted GPU box to a working internal endpoint. Most teams underestimate steps three and four.
- Prep the server: OS, drivers, NVMe layout, network segmentation.
- Install and smoke-test the serving engine (Ollama first, in most cases).
- Stand up the gateway with SSO and audit logging wired to your SIEM.
- If needed, ingest documents into the RAG layer with permission filters in place.
- Wire up front-end integrations: chat UI, internal tools, API consumers.
- Deploy monitoring and write the runbook before calling it done.
Common failure modes cluster around three things: hardware resized too late after underestimating VRAM needs, GPU driver versions mismatched against the serving engine, and retention policy decisions delayed until after logs are already accumulating. Validate the whole stack with a direct call to your /v1/chat/completions endpoint, then run a concurrency benchmark to see actual tokens per second and queue behavior before opening access to real users. Confirm the SIEM export is receiving records, not just that the gateway claims to be sending them.
What Should You Monitor Once Private GPT Goes Live?
Five numbers tell you whether your deployment is healthy: GPU memory utilization, queue depth, tokens per second, request volume per team, and the health of any recent model swap. Exporting these into Prometheus or whatever monitoring stack you already run means you’re not building a second observability system from scratch.
- Set alert thresholds on rising queue depth and falling tokens/sec before users start complaining
- Track per-team volume to catch runaway usage or a misconfigured integration early
- Watch GPU memory for creep that signals a memory leak or an oversized context window setting
Your runbook should fit on two pages: how to restart the serving engine, how to promote or roll back a model version, where the logs actually live, who owns the pager, and a quarterly review cadence. Have someone outside the build team try to follow it cold. If they can’t, it’s not done.
Pro Tip: A runbook that only the person who wrote it can execute isn’t a runbook. It’s a single point of failure with a nicer name.
How Autonomousfirm Partners With Enterprises on Private GPT
A vendor can build the gateway, governance, and operational handoff as one connected engagement rather than treating them as separate purchases. For firms in finance, healthcare, and other regulated sectors, that means the SSO integration, audit logging, and retention policy get designed alongside the model serving layer, not stitched on after a compliance review flags a gap. The team may work inside the client’s infrastructure so the resulting system, code, and data stay owned by the client rather than rented from a vendor. Engagements can end with an internal team fully capable of running the deployment without ongoing dependency on outside engineers.
Perspective: When Self-Hosting Beats a Hybrid Setup
Self-host for steady, sensitive workloads where request volume is predictable and data can’t leave your walls. Go hybrid when reasoning-heavy tasks spike unpredictably and burning GPU capacity on idle hardware makes no financial sense. The decision should track your actual token volume and business process, not a general preference for control.
Most first-year cost estimates undercount the governance work: someone has to own the SSO integration, the retention policy, and the audit exports, and that engineering time belongs in TCO calculations, not treated as a rounding error against the hardware invoice.
— Matevz
Ready to Deploy Private GPT the Right Way?
Most enterprise teams either buy a rented AI tool with none of the data control they need, or try to build a private deployment in-house and discover the governance work takes longer than the model integration itself. A vendor can build the whole system with you, gateway, audit logging, RAG access controls, and the operational runbook, so your team owns a working, compliant production system instead of a proof of concept that stalls at the security review.
The engagement model is built around ownership: your team ends up running the infrastructure, not depending on Autonomousfirm to keep it alive. If regulated data, SSO requirements, or audit obligations are part of your environment, that governance work gets designed in from the first architecture conversation rather than bolted on before launch. Request a technical assessment through Autonomousfirm to scope what a compliant private GPT deployment would look like for your infrastructure, or review the broader build approach at benchmarked to see how the ownership model works end to end.
Sources
For deeper technical grounding, the on-premise architecture guide covers gateway design in detail, the vLLM engineering blog explains logging and API compatibility, BentoML’s on-prem documentation details vector store choices, and Masklabs covers data governance for ingestion pipelines.
- On-Premise LLM Deployment Guide — Production Architecture (LLM Configurator)
- vLLM blog: enterprise deployment and logging
- On-prem LLM deployments | BentoML
FAQ
Can ChatGPT Be Used Privately?
The public ChatGPT product runs on OpenAI’s shared infrastructure, but enterprises can achieve equivalent private functionality by self-hosting an open-weight model behind their own gateway, keeping all prompts and data inside their infrastructure.
How Much Does a Private Instance of ChatGPT Cost?
Costs vary widely by scale, but a departmental deployment typically requires a GPU server in the 80 to 96 GB VRAM range plus roughly one engineer-week of setup time, with ongoing costs weighted toward engineering hours for governance and maintenance rather than the hardware itself.
Is There an AI That Is Completely Private?
Self-hosted open-weight models running entirely on infrastructure you control, with outbound internet access blocked by default, come closest to complete privacy since no prompt or output ever leaves your network. Some companies design these deployments specifically for regulated industries that need that guarantee.
Is There a Private Chat Mode in GPT Deployments?
Yes. A gateway-authenticated internal chat interface, connected to a self-hosted serving engine like Ollama or vLLM, gives each user or team a private, logged chat session that never touches a third-party API.
Should I Start With Ollama or vLLM for a Private Deployment?
Start with Ollama for pilots and light usage under roughly ten concurrent users, then migrate to vLLM once request queuing shows you’ve outgrown single-request serving, keeping the gateway API identical across the switch.